Most professionals stop learning words the way they stop learning songs. Nothing dramatic happens. The habit just fades, and one day the vocabulary you use in a room is the vocabulary you had years ago.
Why it matters
A consultant sells precision. The client feels that something in the process is broken, and the job is to name it so exactly that they nod. Vague words produce vague scopes. Vague scopes produce change orders.
I have sat on both sides of that table. On the shop floor I lived with the results of recommendations written by people who never found the right word for what they saw. Later, writing those recommendations myself, I learned how easy it is to reach for a word that is close and call it done.
Close is expensive. The gap between “inefficient” and “redundant,” between “complex” and “convoluted,” is the gap between a problem the client ignores and one they fund.
Every room has its own language
In a single week I can sit with a controller, a warehouse supervisor, and a field service manager, and hear the same two letters mean three different things. To finance, a PO is a commitment. To receiving, it is a document taped to a pallet. To a project lead, it is the thing that has not been approved yet.
Industry shifts the meaning again. A service order in a manufacturer’s warehouse is not the service order in a field operation. Departments inside one company carry dialects of their own, and nobody announces which one you are hearing. They assume you speak it.
The consultant who nods and moves on builds the solution on a guess. The one who stops and asks learns that two departments have used one word for two different things for years, and that the gap between them is the real problem.
That habit of stopping is what the rest of this post is about.
The problem with looking a word up
Everyone has done this. You meet a word, open a tab, read the definition, nod, and close the tab. Two days later the word comes back and the definition is gone.
A lookup answers the question and throws the answer away. Nothing about the word is kept, and nothing ties it to the work you do. The word stays foreign because you never used it once.
What a lookup lacks is a place for the word to live and a reason to return to it.
The workflow
The process has four steps, and the AI carries most of the weight.
Ask. When a word stops you, in an email, a contract, or a client’s own description of their problem, ask Claude what it means. Plain language, one sentence.
Read the nuance. The definition is the smallest part of the answer. Ask for the origin, the register, and the near words it gets confused with. Is it formal or archaic? What would a careful writer use instead?
Save it. I built a skill that logs the word to a Notion database with the definition, the part of speech, and four example sentences. I copy nothing by hand. I ask once and the entry exists.
Return. This is the step most people skip. The database sorts by date added, so a quick scan of recent words, followed by using one on purpose in a message or a call, turns a record into a habit.
The skill matters more than the model. Any good model can define a word. A skill makes the definition land in the same place, in the same shape, every time, and that is the only reason a habit survives a busy week.
One question becomes one record, and the record sharpens what you notice in the next room.
The skill
The skill is short on purpose. Here it is, with my database link and IDs removed. Copy it, point it at your own database, and change the examples rule to fit the work you do.
---
name: define-word
description: Define a word and log it to a Notion Definitions database with the definition and four example sentences. Use when asked what a word means.
---
# Define a word
When asked for a word (or short phrase) to be defined, do two things: answer in the chat, and record the entry in the Notion Definitions database. Both, every time. The database entry is not optional and is not something to offer or ask about.
## The Notion target
- Database: Definitions
- Properties: Word (title), Definition (text), Part of Speech (select: noun, verb, adjective, adverb, pronoun, preposition, conjunction, interjection, phrase), Example 1 to Example 4 (text), Date Added (created time, automatic, never set it)
## Steps
1. Check for a duplicate. Query the database for an existing row whose Word matches. If one exists, say so and show the existing entry rather than creating a second row. Only add a new row for a different sense of the word.
2. Write the entry. Create the page in the Definitions database.
3. Answer in chat. Give the definition, any useful nuance, and the four examples as a numbered list. Close with a link to the new row.
## Content standards
- Definition: one sentence, plain language, no circular phrasing. Put etymology, register, and commonly confused near words in the chat reply, not in the Definition property.
- Part of Speech: pick the sense being asked about. If the word works as more than one part of speech and the context does not settle it, define the most common sense and mention the other briefly in chat.
- Examples: exactly four, each a complete sentence using the word naturally. Vary the grammatical position across the four (subject, object, modifier, predicate) rather than reusing one frame. Draw at least one or two from your own work, so the word is usable where you will actually use it. Avoid dictionary stock sentences.
- If the word is obscure, archaic, or a technical term of art, say so in chat. That context matters more than the definition itself.
## Multiple words
If several words are asked about at once, create all the rows in a single call, then answer each word in turn.
The examples rule is the part worth customizing. Mine asks for sentences from consulting and delivery work. Yours should ask for sentences from the rooms you actually sit in.
Why four examples
The skill writes four sentences for every word, and each is built differently. The word is the subject in one, the object in another, a modifier in the third, and part of the predicate in the fourth. At least one or two come from my own work: discovery calls, solution design, a Power Platform delivery that slipped.
A definition tells you what a word means. An example shows you where it fits. Four examples in four positions teach the grammar of the word, which is what you need when you reach for it in the middle of a sentence that is already moving.
Sentences from your own world do the rest. A word you can picture saying to a client is a word you will say.
What changes over time
Keep it up for a few weeks and the database stops being a list and becomes a record. You can see which words you reached for, and what they say about the problems you were describing that month.
The second change is quieter. You start noticing words before they stop you. A term you saved weeks ago turns up in a proposal someone else wrote, and you recognize it without opening a tab. That recognition is the lexicon growing.
The AI does not read for you. It removes the excuse to skip the stop.
Start your own
You need three things. A database with columns for the word, its definition, its part of speech, and four examples. An AI that will define a word on request. And one rule: every word you ask about gets saved. Build that rule into a skill or a saved prompt so you never have to decide it twice.
When people ask what makes Power Platform powerful, they point to the tools. Power Apps for the interface. Power Automate for the workflow. Copilot Studio for the agent. After a couple of years of building with it, I think the answer sits somewhere else.
The power is in what the platform rides on.
Power Platform sits on Azure, Microsoft 365, Entra ID, and Dataverse. Identity is solved. Security is inherited. Your users already live in these tools. So the useful question stops being “what can this tool do?” and becomes “what does the Microsoft cloud already do that I can pull in?”
Here is what that looked like in practice.
A word about connectors
In Power Automate, almost everything is a connector. SharePoint is one. Outlook is one. The HTTP action is one too, so calling an Azure Function is still using a connector.
The difference is what each one gives you. A prebuilt connector wraps a service and hands you actions someone else already built: get a file, send a message, create a row. The HTTP action gives you only a pipe. It carries a request out and a response back, and it does no thinking in between.
That distinction shapes everything below. Connectors move data between systems. They don’t interpret it. When a solution needs something understood, calculated, or reshaped beyond what the actions allow, the logic has to live somewhere else, and the flow reaches it through that pipe. Each section that follows is a different answer to the same question: where should this work live?
Power Platform is the front door. Everything beneath the pipe is the Microsoft cloud doing the work.
When no connector understands the work
I needed to run construction takeoffs from CAD drawings. A drawing arrives as a DXF file, and the questions are practical ones. How much floor? How much wall? How many doors? No connector I know of opens a drawing and reports its geometry.
An Azure Function does. It uses a Python library called ezdxf. The flow sends the file over HTTP, the function reads the drawing and walks every entity, the lines, arcs, polylines, hatches, and text labels, and it returns structured JSON: counts by type, total length, enclosed area, and the room annotations. One hospital floor plan came back with more than fifty thousand entities, summarized in a payload a flow can handle.
Then the flow goes back to what it does well. It stores the result, routes it for review, and notifies the right person.
Two lessons came out of it. Files travel in more shapes than you expect. The content can arrive wrapped in JSON, as raw base64, or as a stringified byte object, and my function had to learn to accept all three. And know what your library can read. ezdxf handles DXF and DWG, not DWF, so a different file format meant a different step before the function ever ran.
When the loop is the problem
Some flows turn into nested loops with actions stacked inside each one. They work, but they run slowly and they are painful to maintain.
I moved that logic into functions. One example compared two lists of tasks, treating one as the source of truth, and returned three things: items to update, items to add, items to remove. The flow’s only job was to apply those results through an HTTP call. The function did the thinking and the flow did the delivering.
It also costs less than people expect, and the setup is modest. Secrets go in Key Vault, and the function reads them through a managed identity. The API key never appears in the flow.
When the work outgrows a flow
Contract analysis is one of my favorite examples. A user uploads a PDF to a record in Dynamics 365. A Logic App watches that table, notices the file, downloads it in chunks, and sends it to an Azure Function for analysis. The function is given thirty minutes, because contracts are not quick reading. The result is cleaned, written back to the record, and the user gets an in app notification.
The Power Platform front end stayed simple. The user uploads a file and receives an answer. Behind it, a Logic App, a Function, and a vector store did the heavy work. Nobody on the business side needed to know.
When the answer lives in Excel
This is the one people overlook, and it fits the definition in an interesting way. Running an Office Script from a flow is itself a connector action, the Run script action in the Excel Online connector. The connector is only the pipe. The script is where the work happens.
In one solution, scripts read the column headers from an uploaded file and from the target import template. An AI prompt mapped one to the other, and a final script wrote the clean CSV. A practical note from that build: return arrays from a script as JSON strings. Power Automate will not surface a native array as usable dynamic content, and you will lose an afternoon finding that out.
In another, a script wrote summary values to fixed cells and built a named table, while the bulk rows went in through the Microsoft Graph API using the HTTP with Entra ID connector. Excel stayed the output, and the platform did the rest.
One caution. Office Scripts can be switched off in a tenant, and mine was at first. Know what your environment allows before you design around it.
What reaching costs
Every piece of this has a price, and I do not mean only the invoice.
Logic Apps Standard needs a storage account. Managed identities need role assignments on every resource they touch. Choose a model in Foundry without understanding its pricing, and you can pay for reasoning tokens to summarize an email. I have seen that mistake multiply a cost by seven. I have also cost an organization 23,000 dollars in a single day through one careless configuration. The lesson was simple. Ask questions before you configure, of your stakeholders and of yourself.
Reaching into the platform is worth it. It just is not free, and it rewards builders who know what they are reaching for.
The shift
A solution built on one tool inherits that tool’s limits. A solution built on a platform inherits the platform’s reach.
Power Platform is the front door. The Microsoft cloud is the building behind it. Good architects learn to use the whole building.
My first leader in IT told me something early on: have a checklist. It sounded simple then. It matters more now.
Today an agent can write the code, run the build, and move on before you’ve finished your coffee. That speed is useful. It also makes it easy to lose track of what actually got done.
So I kept the checklist, and I gave it to the agent. Here is the loop.
How it works
The plan builds the checklist. My first prompt produces the plan, and the plan produces the checklist in Notion. One row per build step, in order.
The agent does the work. Each build prompt runs and the code gets written.
The checklist gets updated. The last step in my prompt template says: when you finish, take the summary of what you did and check off the matching rows in Notion. Claude, through an MCP server connected to Notion, does exactly that.
Here is what that looks like partway through a build:
Task
Done
Output
Phase
Prompt
Status
Repo and plan scaffold
✅
Repo, plan doc, ignore file
Foundation
00
Done
Environment discovery
✅
Environment inventory
Foundation
01
Done
Publisher and solution setup
✅
Publisher, solution, variables
Foundation
02
Done
Discovery addendum
✅
Naming and prefix check
Foundation
01.1
Done
Reference tables
✅
Core lookup tables
Data model
04
Done
What I get back:
A running record of where the build stands, without rereading prompt history.
A place to pick up after a break, a meeting, or a long weekend.
A way to review what was completed, not what I assume was completed.
Visibility from my phone, because Notion lives in the cloud and the checklist goes where I go.
The agent does the work. The checklist tells me the truth about it.
Tools change. The discipline doesn’t. Thank you, Dave.
If you build with agents, add one line to your prompt template: when finished, update the checklist.
Most security gaps in Dataverse don’t look like gaps. A reviewer opens a list, sees only their rows, and everyone assumes the boundary is real. A view decides what people see. Filtered record ownership decides what they can reach. I built a small compliance lab in a Dataverse sandbox to test that line, and most of it held. One result did not.
Filtered record ownership is in preview. Microsoft can change how it behaves before general availability, and preview features aren’t meant for production. Everything below comes from a sandbox.[1]
The question every maker asks
Dataverse makers already understand views.
We create views to focus people on the records that matter to their work. We filter them by status, region, legal entity, assigned team, or any number of other attributes. We can even control which security roles see particular public views.
So when Microsoft introduces filtered record ownership, still in preview, a reasonable question follows:
Isn’t this just another way to create a filtered view?
No.
A filtered view decides what appears in a saved list. Filtered record ownership decides which records a user is allowed to access in the first place.[1][2]
The familiar approach
Imagine a custom table called Compliance Evidence.
Each record has a Legal Entity field. You create a public view named US Corp Evidence Awaiting Review with these criteria:
Legal Entity equals US Corp
Evidence Status equals Submitted
You then make that view visible only to the US Compliance Reviewer security role.
That is useful. It gives US reviewers a relevant list and keeps the application easier to navigate. Microsoft supports managing access to public system views through security roles.[2] Two details trip people up: role-based view access only works after an administrator turns on the environment setting EnableRoleBasedSystemViews, and it only applies to public views that aren’t the table’s default view.[2]
A view limited to one security role. It decides who sees the list, not who can reach the data.
But that configuration answers only this question:
Which saved view should this user see in the application?
It does not answer this question:
Which evidence records is this user allowed to access?
Microsoft explicitly distinguishes view access from data access: being able to use a view does not grant access to the records in it, and the user’s underlying Dataverse privileges still control which rows are returned.[2]
The difference
Capability
View limited by role
Filtered record ownership
Primary purpose
Give a role a relevant saved list
Enforce access row by row, based on record values
Filter means
“Show matching rows in this view”
“Authorize access only to matching rows”
Controls
User experience
Data access
Another view can show other rows
Possibly, if normal privileges allow it
No, not for the same restricted identity
API, SDK, or flow access
Normal table permissions determine results
Filter privileges limit results for the identity making the request
System Administrator
Sees whatever the role’s privileges allow
Sees every row, through a built-in “All records” filter
Record owner
Existing ownership model remains
No user or team owner (on tables with Filtered ownership)
Assignment and record sharing
Available when supported by ownership model
Not available because rows under filtered ownership have no owner
Status
Generally available
Preview
Filtered record ownership uses filters assigned through roles as security predicates. Dataverse evaluates the record’s column values against those privileges when deciding whether to allow actions such as Create, Read, Write, Delete, Append, and Append To.[1]
Record filters aren’t limited to the new ownership type. You can also add them to existing tables owned by a user or team, where they grant access on top of ownership rather than replace it.[4]
One filter, two meanings
The same-looking criteria can do two very different jobs.
In a view:
Legal Entity = US Corp
Means:
“When someone opens this saved list, display US Corp evidence.”
In filtered record ownership:
Legal Entity = US Corp
Means:
“A user with this filter privilege is authorized to access only US Corp evidence.”
The criterion is identical. Its role in the platform is not.
A view filter shapes a query. A filtered ownership rule shapes authorization.[1][2]
The view’s filter: Legal Entity equals US Corp and Evidence Status equals Submitted. It decides what appears in this list, not what the user can reach.
Record filters live in their own table. The condition matches the view’s, but here it decides access.
A compliance example
Consider this simple model:
Parent table:Silver Compliance Tracker
Child table:Compliance Evidence
Evidence classification fields: Legal Entity, Region, Sensitivity, and Evidence Status
The parent tracker represents the overall audit, certification, or compliance cycle. It can remain a normal table owned by a user or team, because there may be an accountable compliance manager or team.
The child Compliance Evidence table represents individual evidence items. This is where filtered ownership earns its place, because access may need to depend on the evidence item’s classification rather than who owns it.[1]
For example, the US Compliance Reviewer role might receive a record filter:
Legal Entity = US Corp
An EU Compliance Reviewer role might receive a different record filter:
Legal Entity = EU GmbH
Now the US reviewer may see the overall tracker but only the evidence items that match the US filter. The EU reviewer sees only EU evidence. That is need to know, enforced by the platform.[1]
The lab: Silver Compliance Tracker is the parent, and Compliance Evidence is the child that carries the record filters.Record ownership: Filtered (preview). The field is greyed out because the choice is permanent once the table exists.
What I tested
Documentation tells you what a feature should do. A lab tells you what it does. So I built this model in a Dataverse sandbox and tried every route I could find. The setup:
The two tables above, with Compliance Evidence created as Filtered ownership
Two record filters (US Corp and EU GmbH) and two reviewer roles, each granted its own filter
Six evidence rows: three US Corp, two EU GmbH, and one Canada Ltd row that no reviewer filter covers
The same data surfaced through a model-driven app, the Web API, a Power Automate flow, a code app, and a Copilot Studio agent
One test user without admin rights, switched between the two roles
The clearest result is the second row of the table below. The Evidence Submitted view has no Legal Entity filter at all, yet each reviewer still saw only their own entity’s rows. The record filter did that, not the view.
Route
US reviewer
EU reviewer
System Administrator
View: All Compliance Evidence
3 rows
2 rows
6 rows
View: Evidence Submitted (no Legal Entity filter)
2 rows
1 row
4 rows
View: US Corp Evidence Awaiting Review
In the list, 2 rows
Not in the list; 0 rows when opened through Manage and share views
2 rows
Other entity’s record by direct link or Web API
Not returned
Not returned
Returned
Web API list
3 rows, all US Corp
2 rows, all EU GmbH
6 rows
Power Automate flow (run as the user)
3 rows
2 rows
6 rows
Code app
Own rows only
Own rows only
Not tested
Copilot Studio agent (Authenticate with Microsoft)
Own rows only
Own rows only
Not tested
Create a record for the other entity
Blocked
Blocked
n/a
Change own record’s Legal Entity to the other entity
Allowed
Allowed
n/a
The last row is the one that matters most. I come back to it below.
The administrator column is a warning, not a feature. Dataverse automatically gives the System Administrator role a built-in “All records” filter on every filtered table, so an admin always sees everything. If you test with an admin account, you prove nothing.[1]
The agent result is what I observed in one test, not documented behaviour. Treat it as something to verify in your own environment.
US Compliance Reviewer Role
EU Compliance Reviewer RoleThe view opened. The records didn’t. The EU reviewer’s filter blocks US Corp evidence, whichever view they use.The view isn’t the boundary.Signed in as the EU reviewer, I asked the Web API for a US Corp record by its ID. Dataverse refused. RecordFilterAccessRights: None. No filter granted access, so no record.Signed in as the EU reviewer, the code app shows three rows, all EU GmbH. The app doesn’t filter anything; the record filter does. The third row started life as US Corp evidence. A US reviewer moved it here, which is the edit problem covered below.Signed in as the EU reviewer, I asked the agent for everything. It returned three EU GmbH records and found nothing for US Corp or Canada Ltd. The agent never saw those rows, so it couldn’t leak them.
The security layer
So what is it, then? A security control at the data layer, for reading and creating records.
A user cannot get around the filter simply by selecting a different view. Whether the user reaches Dataverse through a model-driven app, a code app, the Web API, or a flow that runs as that user, Dataverse evaluates the same filter privilege.[1] In my tests, every one of those routes returned the same rows for the same role.
When a client asks, I put it this way:
A view controls the screen. Filtered ownership controls the record.
Or:
Views organize data; filtered ownership authorizes data.
An important qualification
Dataverse always evaluates the permissions of the identity making the request. That sounds obvious until you meet a cloud flow.
A flow does not run as the person who presses the button by default. It runs with the connections saved in the flow, which are usually the maker’s. In my lab, the Evidence Read Test flow returned all six rows to every user until I opened the flow’s Run only users panel and set the Dataverse connection to Provided by run-only user. Only then did it return three rows for the US reviewer and two for the EU reviewer.[3]
Two details matter:
The connection’s account needs a privilege. For Dataverse in the same environment, “provided by run-only user” makes Dataverse act on behalf of whoever runs the flow. The account behind the flow’s Dataverse connection must hold Act on behalf of another user (or the Delegate role). When I pointed the flow at a connection for a regular user, saving failed with a missing prvActOnBehalfOfAnotherUser error.[3]
Data that leaves Dataverse leaves the filter behind. A flow co-owner can open the run history of someone else’s run and read everything that run returned. In my lab, that meant all six evidence names, including rows the co-owner’s own role could never read. The filter protects rows in Dataverse. It does not protect copies of them in run history, exports, emails, or logs.
A flow or integration running under a service account, application user, or service principal is the same case: a separate security principal with its own permissions. That does not bypass security, but it can return more than an individual reviewer could see.[5][1]
So the honest version is:
Filtered ownership applies consistently everywhere Dataverse evaluates the same identity’s permissions. Check which identity each route actually uses.
Run as the administrator: count 8. The flow returns every evidence record, US and EU alike.The same flow, run as the EU reviewer: count 3. Same steps, same query. The only thing that changed is whose identity Dataverse checked.
One flow, two answers. As the administrator, it returns 8 records. As the EU reviewer, it returns 3. The flow didn’t change. The identity did.
A gatekeeper on create, not on edits
The filter is not auto-fill
Filtered ownership does not automatically populate fields.
Suppose a US reviewer can create only records where:
Legal Entity = US Corp
The application still needs to set the Legal Entity field, through a form default, Power Fx, automation, a plug-in, or another controlled process. The filter acts as a gatekeeper: it allows the new record only if its value satisfies the user’s Create filter.[1] In my tests that held. Each reviewer could create a record for their own entity, and an attempt to create one for the other entity was refused.
The filter is a gatekeeper, not an auto-fill rule.
When it fits
Filtered ownership is useful when access should follow a trustworthy record attribute:
Legal entity
Geographic region
Data classification
Customer segment
Business division
Control area
Regulatory scope
This makes it useful for need-to-know scenarios, provided those classification fields are required, accurately maintained, and governed. The security rule is only as reliable as the data used to evaluate it, and, as the edit test shows, only as reliable as the controls on who can change that data.[1]
When teams still fit better
Filtered ownership is not a replacement for tables owned by a user or team.
Use a traditional design built on ownership when you need:
A clear individual or team accountable for each record
Assignment and reassignment
Record sharing
Ownership-based processes and reporting
A regional or functional team that truly manages the work
Use filtered ownership when the central access question is:
“Does this record’s classification authorize this person to access it?”
Use team ownership when the central question is:
“Which person or team is responsible for this work?”
The two aren’t mutually exclusive. A table owned by a team can also carry record filters that grant extra access, based on record values, on top of ownership.[4]
Choose the pattern that matches how the work runs, not the one that shipped most recently.[1]
Where the boundary lives
Filtered record ownership is not a new way to make filtered views.
It is a different security model for custom tables, one where a record’s values, rather than a user or team owner, determine who can access it.
A view limited by role may still be valuable. It gives each user an appropriate experience and reduces navigation clutter. But it does not establish the data boundary.
Filtered record ownership is still in preview, and that matters more than it sounds. A table’s ownership type can’t be changed once it’s created, so a table you build on it today is a commitment to a feature that isn’t finished. The edit behaviour above is exactly the kind of detail that may change before general availability. Approach it as a sandbox exercise and a pattern to evaluate, not yet a production security foundation.[1]
The view says, “Start here.”The filtered ownership rule says, “Only these records.”Your own controls on the classifying field say, “And they stay that way.”
Some books arrive without a reason. Someone tells you to read it, you take their word, and a few chapters in you are turning pages while nothing lands. You never learned what you were looking for.
Understanding a book starts with understanding why you are reading it. Without that, you finish with a few highlights and a vague sense of having been in the room. With it, every chapter has a job to do.
I ran into this with Capitalism and Freedom by Milton Friedman. It was recommended to me, and I opened it with no clear sense of why it mattered. I could have read on and hoped the reason would surface. Instead I decided to build the reason first.
The workbook
The workbook is a PDF that AI builds for me before I read the first page. Every book gets the same structure.
The first page is an abstract: what the book is, when it was published, who wrote it, the themes that keep returning, and how to read it. For Friedman, the instruction is to read it as an argument. That one line changed my approach. I stopped collecting facts and started tracking claims and the evidence behind them.
Each chapter then gets its own page. At the top is a single line: why am I reading this? Below it are three questions to carry into the chapter and answer as I go. At the bottom is an open notes section for everything the questions did not anticipate.
The back of the workbook holds two tools. The first is a page of key terms, the concepts the book depends on. The second is a vocabulary log with three columns: the word, the page where I found it, and what I think it means in my own words.
Why the pen
Writing by hand slows me down in the right places. I upload the PDF to my reMarkable Paper Pro and write directly on the pages.
Typing is fast, and fast is a problem when the goal is understanding. A keyboard lets me transcribe a thought without ever holding it. The pen forces a decision about what is worth the effort of writing. An answer to a chapter question has to pass through my mind and my hand before it reaches the page, and that is where the learning happens.
I think of it as a touch point. The book is in front of me, the pen is moving, and the two stay connected. The device keeps the feel of paper, and the PDF keeps everything for one book in a single file I can carry anywhere.
The division of labor
AI builds the structure, and I do the thinking.
The model was trained on a great deal of written literature, so it is well placed to say what a book argues, where it sits, and what a careful reader should watch for. That is scaffolding. It tells me where to look.
It cannot do the looking. The answers on the page are mine. The definitions in the vocabulary log are in my own words, written before I check anything. If the same tool that built the workbook also filled it in, I would own a tidy document and no understanding.
There is one limit worth stating plainly. The model builds from what it knows about a book, not from the pages in my hands. When I asked for vocabulary from each chapter, it could not pull words from my edition. So the key terms page covers the core concepts of the book, and the vocabulary log stays blank for me to fill as I read. I would rather have an honest blank than a confident guess.
Build your own
You can set this up for any book in a few minutes. Start with this prompt and replace the brackets.
I am reading [title] by [author]. Build me a printable reading workbook as a PDF.
Page 1: an abstract covering what the book is, when it was published, who wrote it, its recurring themes, and how I should read it.
For each chapter, one page with a line at the top asking why I am reading this chapter, three questions to answer while I read, and an open notes section.
At the end: a page of key terms to know, with the chapter where each appears, and a blank vocabulary log with columns for the word, the page I found it on, and what I think it means in my own words.
Leave plenty of room to write by hand. If you cannot source something from the book itself, say so and leave it blank.
The tool matters less than the sequence. Decide why you are reading, write it down, then let the book answer.
For part of my career I worked the line at a cabinet plant. Now I am the one who walks in with a deck, a set of questions, and a recommendation. I know both views, and I have come to believe the second one forgets what the first one knows.
What the redesign got right, and what it missed
At the plant, the line was redesigned to increase productivity. The logic was clean. The responsibilities in each cell were divided in half, so each person had less to do and the work moved faster.
On paper, it worked. We produced more cabinets.
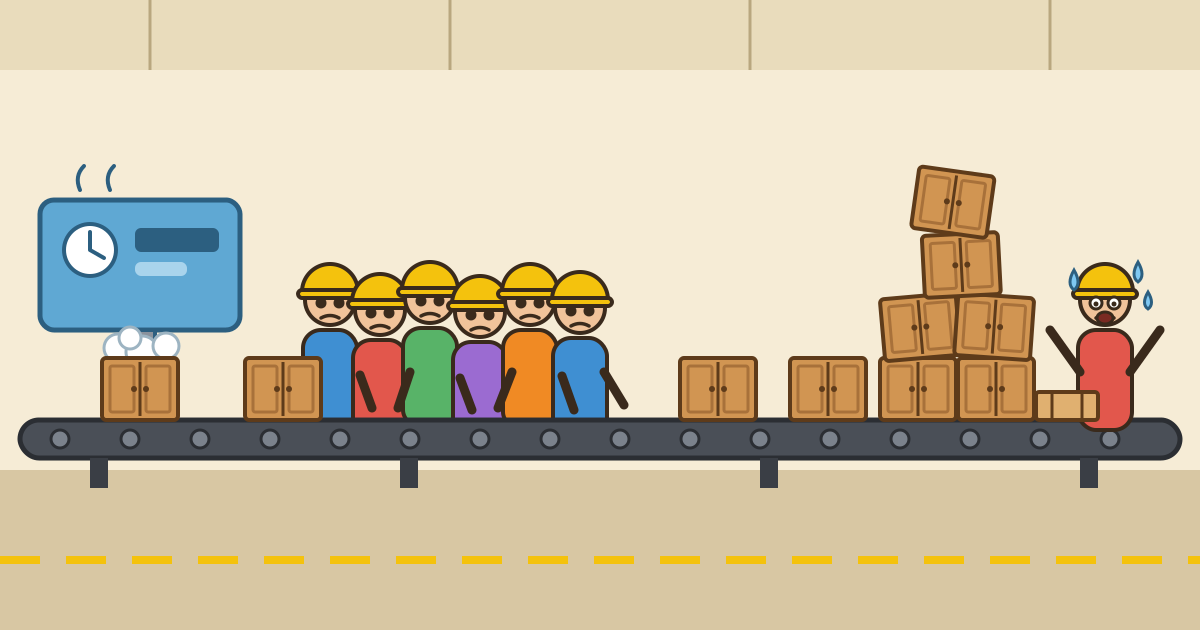
Then the floor started to change. Splitting the work meant adding people, and more people meant tighter space. Moving around the line got harder. The extra hands that were meant to speed things up were now in each other’s way.
The next problem showed up at the end of the line. We were building more cabinets than one person could crate. All the speed we had gained piled up at a single station, and that one person became the bottleneck for the whole operation. The line could only run as fast as the crating allowed.
Then there was the foam. The foaming machine insulated the cabinet, but the foam needed time to set and cure before anyone could work on it. That wait introduced variance into production. Some cabinets were ready when the next cell needed them. Others were not. The rhythm the redesign promised kept breaking in small, unpredictable ways.
None of this was visible in the plan. All of it was visible to the people standing on the floor.
What we are trained to see
Consultants are hired for expertise, and we earn it. We learn to run discovery, ask sharp questions, and gather requirements with discipline. We map the process, find the gap, and design the answer.
But gathering requirements is not the same as living inside them. A requirement is a sentence on a page. For the person doing the work, it is Tuesday morning, a full queue, a crowded aisle, and a supervisor asking why the numbers moved.
If our whole career has been spent collecting the story of the work, we can mistake the story for the work.
The job behind the task
This is where the Jobs to Be Done approach earns its place. The idea is simple. People do not adopt a solution because of its features. They bring it into their work to get a job done. If we want to understand why something succeeds or fails, we have to understand the job.
The redesign at the plant focused on the task: make each cell do less. But the job was larger than that. The job for the people on the line was to build a cabinet to standard, keep their pace, avoid rework, and finish the shift without fighting for space. The job for the operation was to get finished cabinets out the door.
A redesign can improve a task and still damage the job. We made one step faster and made the whole system harder to run.
That is the question I try to ask now, before any recommendation: what job is each person trying to get done, and does this change help them do it or get in the way?
Asked early, that question surfaces the things a process map hides. How much room people need to move. Where work will collect when one step speeds up. What waits, like curing time, will do to the rhythm. Those are not edge cases. They are the job.
Where the recommendation lands
A recommendation does not stay in the conference room. It travels. It becomes a new layout, a new approval step, a changed routine, a number someone will now be measured against.
The people who receive it were rarely in the room when it was shaped. They find out what we decided when it shows up in their day. Some will see the logic right away. Others will see one more thing added to a job that was already full.
I know the quiet that settles over a floor when a change is announced and nobody has been asked a question about it. That quiet is not agreement. It is people deciding how much to say.
What we owe
I think our responsibility to the client has three parts.
Understand the job, not just the process. Spend time where the work happens. Ask people what slows them down and what they would never want to lose. Watch the movement, the waiting, and the workarounds. A workaround is not a violation. It is the floor telling us where the design fell short.
Look past the step you are improving. Every gain moves pressure somewhere else. Before we celebrate a faster cell, we should know where the work will pile up next, and who will be standing there when it does.
Stay accountable after the handoff. The engagement ends on our calendar. For the client, it begins there. We owe them our attention through the stretch when the new way is harder than the old way and trust is thin.
The people side is the work
I do not see the people side as soft. It decides whether the technical work survives.
A well built solution that people resent will be worked around, then abandoned, then quietly replaced. A good solution that people helped shape will be defended, improved, and carried forward by the ones who live with it.
That is the difference between delivering something and leaving something behind.
What I try to remember
Before I make a recommendation, I picture the person who will receive it. Not the executive who signed the statement of work, but the one standing at the line, the counter, or the desk. I ask what job they are trying to get done, and whether I would be willing to work inside what I am about to propose.
If the answer is yes, I put it forward with confidence. If the answer is no, I have more work to do.
We are hired to know things. We are trusted when we remember who we know them for.
Every few weeks, a new model or feature ships, and by the afternoon something has been canceled.
A tool. A category. Sometimes an entire profession. The timeline moves on before anyone asks what the claim rests on.
I’ve watched this pattern repeat across Anthropic releases, Grok, and every other model that lands with a good demo. The announcement is real. The verdict that follows it usually isn’t.
The server room nobody tweets about
In 2019, I joined my first IT team. We were running SQL Server 2016.
Nobody on that team was careless. The system worked, the data was governed, the integrations were tested, and the people responsible for uptime had no reason to trade a stable thing for a newer one. The upgrade was on the roadmap. It just wasn’t on the roadmap yet.
That is what adoption looks like inside an organization. It moves through budget cycles, security reviews, compliance sign off, retraining, and the quiet math of what breaks if something changes. The vendor’s release date is the beginning of that process. It says nothing about the end.
The Unix box that wouldn’t die
There was also a Unix box.
It sat in the corner of that same environment, running long after anyone would have chosen it, and it kept running. They don’t build them like that anymore. It held legacy data, and the presales engineers and technical engineers reached for that data in their daily work. Nobody was nostalgic about it. They used it because the answers they needed were there.
When something did go wrong, I didn’t open a ticket with a vendor or search for a tutorial. I called one person. He worked on Unix systems, and he would remote in, look around, and fix it. He had built a career on knowing machines that the rest of the industry had already declared finished.
That stays with me. If a technology is dead, no one is paid to keep it alive, and no one gets a call when it breaks. But there was a man whose phone rang because the engineers still depended on what that machine held.
Someone’s career was proof of life.
Two clocks
Announcements run on one clock. Enterprises run on another.
The first one measures in weeks. The second measures in years. Some of those years belong to a whole profession. There are people who spend a career keeping the older systems standing, and the businesses that rely on them are glad they exist.
When we say a product is canceled, we’re reading the fast clock and applying it to the slow one. We treat a signal about the future as a fact about the present.
Most of what gets called canceled is still running payroll, moving inventory, and closing the books at companies that will not change it this year, and shouldn’t have to.
What the verdict costs
This isn’t harmless. When the timeline declares something dead, someone in a leadership meeting hears it and asks why we’re still using it.
Now a team that made a sound decision has to defend it against a demo. Clients start to feel behind for staying with tools that still deliver. Money moves toward replacement projects that solve nothing the old system wasn’t already solving.
I sit in these rooms. The pressure to rip and replace almost never comes from a failed workload. It comes from a headline.
Where the other side is right
New capabilities do change things. For a project starting today, the build or buy decision may look very different than it did last year. Some tools will fade, and a few will fade quickly.
But that’s a statement about new work. The installed base is a different question, and it gets answered slowly, with evidence, one migration at a time.
A better standard
Before I say something is canceled, I try to answer four questions:
What share of real workloads has the new product actually displaced?
What does it cost an organization to switch?
Does it replace the old system, or does it change the calculus for new builds?
Where is the adoption data, and not just the demo?
If I can’t answer those, I haven’t found a death. I’ve found a release.
Technology rarely gets canceled. It gets outgrown, then outlasted, then quietly retired years after the conversation moved on. The people running it deserve better than a verdict that arrived before the evidence did.
One of the fastest ways to build a bad platform strategy is to turn a platform you like into the answer for every problem.
That is usually where good intentions begin creating long term complexity.
The purist answer is, “We can build it.” The practitioner’s answer is more useful: let products do what they are already good at, and be intentional about what you add around them.
That matters even more now. AI is changing how people interact with business systems, and Power Platform can connect to APIs, events, data sources, and existing applications. In that world, rebuilding a product’s core capability is rarely as inventive as it sounds. More often, it means recreating something the organization already owns, then accepting the responsibility to maintain it forever.
For example, I do not need to build a full project management product in Dataverse just because I want better delivery governance. The project management platform can continue to own schedules, tasks, assignments, and dependencies. Dataverse can own the governed operational work around it: engagement health, delivery risks, decisions, approvals, exceptions, portfolio reporting, and the automations that connect delivery activity to leadership and other systems.
Dataverse does not need to be everything.
It needs to be the right thing: the governed operational layer for work that requires structure, ownership, security, workflow, automation, and reuse across the organization.
That is the real decision in front of us.
Not, “Can Dataverse store this?”
It usually can.
The better question is, “Does this work need the kind of governed, connected, actionable operational data platform that Dataverse provides?”
Some work needs a place to be discussed. Some work needs a place to be documented. Some work needs a place to be analyzed.
But some work needs to be owned.
It needs structure. It needs a lifecycle. It needs accountability. It needs to move through a process, trigger action, respect security boundaries, and remain available to the next application, flow, report, integration, or person that depends on it.
That is the kind of work that belongs in Dataverse.
Look for the Signals
There will be signs.
Including Dataverse in a solution architecture should be an intentional decision, not a reflex. Certain signals tell us when work has outgrown a simple list, spreadsheet, or lightweight collaboration tool.
And, to be clear, these signals are not exclusive to Dataverse.
Meaningful relationships. A defined lifecycle. Different levels of access. Automation. Auditability. Reuse across applications and systems. Data that drives action or decisions.
Those signals do not automatically mean, “Use Dataverse.”
They mean the work deserves an intentional operational architecture.
Dataverse may be that architecture. Another product may already own the domain. Or Dataverse may become the governed layer around the system that remains authoritative.
The question is not whether Dataverse can store the data. The question is what should own the work, and what role Dataverse should play around it.
When several of these conditions appear together, the work is telling you something. It is no longer just information someone wants to keep. It is becoming an operational process: something that coordinates people, carries responsibility, moves through stages, triggers decisions, and needs to remain dependable after the original maker has moved on.
That is when we need to slow down and look carefully at the data, the process, the people involved, and the systems that already own part of the work.
A workstream may be ready for a more intentional operational foundation when several of the following statements are true.
Signal
What it means
Meaningful relationships
Start with the data model. Does the work involve more than a flat list? Are there customers, projects, requests, approvals, tasks, risks, decisions, and documents that need to relate to one another?
A defined lifecycle
Does the record move through recognizable states, handoffs, decisions, exceptions, or approvals that the business needs to understand and trust?
Different responsibilities require different access
Do different people need different levels of control over who can create, view, update, approve, assign, share, delete, or export the information?
The process needs dependable action
Do status changes, thresholds, dates, or decisions need to trigger automation, notify people, update another system, or create the next step in the process?
The organization needs accountability
Does the business need to know who changed something, when it changed, and sometimes why a decision was made?
The same record must be reused
Does the same record need to appear in multiple apps, flows, reports, agent experiences, or integrations without creating competing versions of the truth?
The data drives decisions
Is the information used to approve funding, escalate a delivery issue, manage risk, prioritize work, or run part of the business?
The presence of these signals is not a shortcut to a product decision. It is a prompt to design intentionally.
Sometimes Dataverse should be the foundation. Sometimes the product already built for the domain should remain the system of record. And sometimes the best architecture is a partnership: the authoritative system continues to own the core domain, while Dataverse owns the intake, governance, approvals, exceptions, coordination, reporting, and automation that make the work manageable across the organization.
That is the measure of a healthy architecture: each platform has a clear job, each important record has a clear owner, and the organization can explain why the work lives where it lives.
Work Dataverse Owns Directly
As I mentioned earlier, Dataverse can be the foundation, or it can be an extension.
One example I see often in Dataverse is intake processes. This work may not live anywhere else. It may not belong in an ERP, CRM, IT service-management platform, or another specialized product.
It may be unique to how the organization operates: how it receives an idea, request, opportunity, concern, exception, or assessment; how it decides what matters; who needs to review it; what evidence is required; and what happens next.
That is where Dataverse can become the foundation. It gives the organization a governed place to create the record, assign ownership, move it through a lifecycle, apply its rules, capture decisions, and understand the current state of the work.
Change Requests
Consider an organizational change request.
A team may identify a policy that no longer works, a handoff that creates delay, a control that creates unnecessary friction, a role that is unclear, or a customer-facing process that needs to change.
That is not necessarily an IT service request. It is not automatically a project task. And it may not belong in an ERP, CRM, or another specialist product.
It is a request to change how the organization operates.
The request needs to be understood and assessed. What is changing? Why does it matter? Who is affected? What processes, systems, controls, roles, or teams will be impacted? What risks does the change introduce? Who has the authority to approve it? What needs to happen before the change can take effect?
Dataverse can own that record from submission through impact assessment, review, decision, implementation, and outcome. It gives the organization one governed place to see the proposed change, accountable owner, affected stakeholders, supporting evidence, approval history, actions, and final result.
That is not a shadow ITSM process. It is the organization governing changes to the way it operates.
Work Dataverse Can Own Within a Larger Process
So what does that kind of work look like in practice?
It is usually not a single task, a static document, or a piece of information someone wants to keep nearby.
It is shared operational work. It has records that relate to one another, people with different responsibilities, and a lifecycle the business needs to trust. It includes decisions, actions, exceptions, and outcomes that matter beyond one person or one team.
Dataverse is often a strong fit when that work needs a durable, governed home and does not already belong to a product designed to run the domain.
That distinction matters.
The goal is not to move work into Dataverse because we can. The goal is to put operational work where the organization can secure it, automate it, reuse it, report on it, and maintain it over time.
Invoice Preprocessing
One example I have worked with is invoice preprocessing.
I would not advocate rebuilding accounts payable in Dataverse. The ERP should own the vendor invoice, the financial transaction, the accounting controls, and the eventual payment. That is what ERPs are built to do.
But there may be work that needs to happen before an invoice enters the ERP.
Dataverse is well positioned to handle that work. The invoice may need to be reviewed. Information may need to be validated. An exception may need to be resolved. More than one person may need to examine it, and it may need to move through a series of approvals before finance is ready to accept it.
That is not a replacement for the ERP. It is the governed operational process around it.
If we look back at the signals, this is where they become easier to see:
Signal
How your invoice process demonstrates it
Meaningful relationships
An invoice relates to a supplier, requester, cost center, purchase order or business context, approval requests, approvers, and eventually an ERP record
Lifecycle
Received → reviewed → routed → pending approval → approved or rejected → submitted to ERP → processed or exception
Different permissions
An AP processor, budget owner, approver, finance reviewer, and platform administrator do not need identical access
Dependable automation
The process needs routing, approval notifications, reminders, outcome handling, ERP submission, and error notification
Auditability
Finance needs to understand what was submitted, who approved it, when approval occurred, and why it was rejected or escalated
Data reuse
The invoice may appear in a model-driven app, approval experience, flow, finance report, exception queue, and ERP integration
Operational decisions
A person decides whether the invoice is valid, whether an exception needs attention, and whether funds or payment should be approved
That is the pattern when Dataverse owns the work. The harder discipline is knowing when it should not.
Work That Should Stay Elsewhere
My desire to make Dataverse the backend technology for the system of all systems began with some naivete.
Trust me, it was humbling to learn the limitations of Dataverse. But those limitations are worth noting.
Not because they make Dataverse less valuable, but because they force us to be more deliberate about what it should own and what should stay elsewhere.
Dataverse can store relational data. It can secure records. It can power applications, automation, reporting, integrations, and increasingly AI-enabled experiences.
But it is not a replacement for every system, every workload, or every collaboration pattern. It is not an ERP. It is not a document-management system. It is not an IT service-management platform. It is not a warehouse or lakehouse. It is not the best place for every note, task, file, transaction, or historical record.
The mistake is not using Dataverse. The mistake is treating capability as a reason for ownership. Just because Dataverse can store a record does not mean Dataverse should become the system that owns it.
Core Business Transactions
ERP has its place at the system of record for a reason.
An ERP is not simply a database with forms and approvals layered on top. It is built to run the organization’s core business transactions.
The general ledger. Purchase orders. Vendor invoices. Payments. Inventory movements. Customer orders. Billing. Fixed assets.
These are not just records with fields and statuses. They are transactions governed by accounting rules, financial controls, procurement policy, tax treatment, inventory costing, budget commitments, period close, audit requirements, and years of embedded business logic.
Rebuilding that behavior in Dataverse because Dataverse can model tables, relationships, workflows, and approvals is not innovation. It is taking responsibility for a domain the ERP was built to run.
Dataverse can still create real value around those transactions. It can own intake, preprocessing, exception handling, business-specific review, cross-functional approvals, tailored experiences, and automation. But the ERP should remain authoritative for the transaction itself.
Dataverse can coordinate and extend the work around the transaction. The ERP runs the transaction.
Specialized Operational Domains
The next category is specialized operational work.
Some work is not generic enough to rebuild from tables, forms, and flows without giving up the capabilities that make the specialist product valuable.
A service-management platform is not simply a ticket table. A project-management platform is not simply a task table. A contract-lifecycle-management system is not simply a document plus approval. A field-service platform is not simply appointments, work orders, and assets.
These platforms embody years of domain knowledge: service-level management, queues, change control, configuration relationships, resource scheduling, project dependencies, contract clauses, dispatch, maintenance plans, inspections, and controls specific to each industry.
Dataverse can integrate with these systems. It can create a governed process around them. But it should not become a shadow replacement just because a team wants one more app.
Work that should remain in a specialized platform
Why it belongs there
Appropriate Dataverse role
IT incidents, changes, problems, service requests, CMDB
ITSM platforms manage service levels, ticket lifecycles, change control, configuration items, and operational support
Business-demand intake, governance review, executive reporting, or cross-functional exception process
CLM products specialize in contract language, workflows, redlining, signing, and legal records
Intake, related initiative or vendor context, downstream operational obligations
Field dispatch, route optimization, maintenance scheduling, technician mobility
Field-service and asset-management products handle work orders, dispatch, service history, inventory, and maintenance
Supplemental inspection, custom governance, exception workflows, and business reporting
Security operations, alerts, investigation, and incident response
Security platforms are designed for telemetry, detection, correlation, response, and evidentiary investigation
Risk or compliance reporting around the security process, where appropriate
Large Scale Analytics and History
Dataverse should not become the organization’s default data lake, warehouse, or analytical archive.
A current operational record may belong in Dataverse. But years of transaction history, telemetry, application logs, clickstream behavior, IoT data, machine data, event streams, and enterprise-wide reporting workloads are different kinds of work.
They need ingestion pipelines, transformation, partitioning, broad historical retention, analytical engines, scalable compute, data science tools, and access patterns built for questions across millions or billions of records.
That is where Fabric, a lakehouse, a data warehouse, Azure Data Explorer, Databricks, or another analytical architecture belongs. Dataverse can remain the place where a user acts on a current operational issue. The analytical platform can be the place where the organization detects the pattern that revealed the issue.
High Scale Digital Products and Event Workloads
Finally, Dataverse is not automatically the backend for a high-scale digital product.
A public consumer application, marketplace, high traffic website, mobile product, telemetry platform, or real time event processing system may need global distribution, high throughput, low latency APIs, custom caching, event streaming, specialized search, independent deployment, and direct control over the application stack.
Those needs may point to Azure SQL, Cosmos DB, PostgreSQL, Redis, Azure Functions, Event Hubs, Service Bus, API Management, or a custom cloud architecture.
Dataverse may still participate. It may hold governed business records, customer-service context, internal operational workflows, or application-administration processes. But it should not be selected simply because it is the Microsoft data platform most familiar to the team.
A Power Pages site can absolutely serve a serious external audience. High traffic alone does not disqualify Dataverse or Power Pages.
The question is what kind of work the site is doing. Power Pages is a strong fit when the website is the front door to a governed business process: a partner request, application, case, inspection, onboarding process, or other Dataverse-owned operational record.
But when the digital product itself becomes the workload – when it depends on extreme transaction volume, real-time interaction, high-frequency events, specialized search, global-scale performance, or deep control over the application stack – a custom cloud architecture may be the better foundation.
Dataverse may still play a role. It may hold governed records, internal administration, exceptions, or human-review workflows. But it does not need to carry every request, event, click, or transaction just because the application is built on Microsoft technology.
Lightweight Work
And then there is work that should stay lightweight.
Not every early idea, personal task, team note, workshop output, or draft document needs lifecycle controls, security roles, relationships, integration, or audit history. Those tools are still valuable. They simply solve a different problem.
Dataverse Can Own, Extend, or Participate
By now, the question should not be, “Should this live in Dataverse?”
The better question is, “What role should Dataverse play in this process?”
There are three useful answers. Dataverse can own the work. It can extend the work. Or it can participate without becoming the system of record.
Dataverse role
What it means
Example
Own
Dataverse is the authoritative operational record from intake through decision, action, outcome, and closure
An organization-specific improvement request, policy exception, solution-readiness review, compliance attestation, or custom inspection
Extend
Another system remains authoritative for its core domain; Dataverse owns a distinct workflow around, before, or across that system
Invoice preprocessing and approvals before ERP payment; ERP exception management; cross-functional approval and review
Participate
Another platform owns the record; Dataverse contributes selected records, workflows, apps, reporting, or integrations without creating a duplicate source of truth
A Power App reads ERP data; Dataverse tracks a related business decision; an integration surfaces approved information elsewhere
The unhealthy answer is duplication.
If the ERP owns the invoice, do not create another competing invoice record in Dataverse. If the project-management product owns the schedule, do not create a shadow schedule in Dataverse. If SharePoint owns the document, do not create a second document repository. If an ITSM platform owns the incident, do not create another ticket queue.
The architecture becomes durable when each platform has a clear job, each critical record has a clear owner, and the organization can explain the boundary in one sentence.
A useful architecture test is this: Can we explain, in one sentence, what each system owns?
If we cannot, we are likely creating duplicate records, conflicting processes, unclear accountability, and a future debate about which system is the source of truth.
In the invoice example, the explanation is simple: Dataverse owns the review, exception, and approval workflow before the ERP transaction; the ERP owns the vendor invoice, financial posting, and payment.
That is a healthy boundary.
Dataverse does not need to be the database for every application or the backend for every system.
It is most valuable when it gives governed operational work a durable home: work with shared ownership, relationships, lifecycle, security, automation, accountability, and a need to connect people and systems.
Sometimes it owns that work directly. Sometimes it extends the system that owns the core transaction. Sometimes it participates without owning the record at all.
The point is not to maximize the amount of data stored in Dataverse. The point is to create an architecture in which important work has a clear owner, a clear lifecycle, and a trusted source of truth.
Bridge to Part 4
We will close out this Dataverse series in Part 4.
By then, we will have established that Dataverse does not need to own every kind of work. But when Dataverse does own the governed operational record, another question remains: where should people experience and collaborate around that information?
A source of truth is not defined by where data is visible. It is defined by where the organization governs, maintains, and trusts that data.
In the final part of this series, I will explore what it looks like to keep Dataverse as that governed source of truth while surfacing selected, approved information in Notion…giving people a more flexible work experience without turning Notion into an uncontrolled replacement for the system of record.
My wife doesn’t use Claude. She doesn’t use ChatGPT either, not directly, not by name. What she says, almost every time a question needs more than her own head can give it, is some version of the same line: “Let’s see what Copilot says.”
Not Claude. Not ChatGPT. Copilot. Every time.
I’ve built a career around Microsoft’s ecosystem. I know the gap between these tools is thinner than the marketing around them suggests, and I could make an argument for why one might suit a given task better than another. But that isn’t what struck me about her sentence. What struck me is that she never asks which AI to use. She has one. It’s the one she has. The question of alternatives never enters the room.
And I think that’s the healthier instinct.
Somewhere in the last two years, picking an AI tool turned into a small identity decision. People defend their choice the way they’d defend a phone or a browser or a car. Claude people talk about writing quality. ChatGPT people talk about breadth. Copilot people talk about what’s already sitting inside the software they use all day. Every camp has a reason, and every reason is a little bit true, and none of them matter nearly as much as the conversations happening around them suggest.
Here’s the part worth sitting with: my wife gets useful answers. Reliably. Without ever wondering if she picked the right poison. She picked one, and then she moved on to the actual problem she was trying to solve.
That’s the piece a lot of us lose once we know enough to have opinions. Knowing the differences between these tools is genuinely useful when you’re the one deciding what to build on, what to integrate, what to put in front of a client. That’s my job, and I won’t pretend the choice never matters. But for most people, most days, the tool isn’t the bottleneck. The question they’re asking is.
I’ve watched people stall out entirely because they’re not sure they’re using the “right” one. They’ll wait, or ask around, or read another comparison post, before they’ll just open whichever tool is already sitting on their desktop and ask their question. That hesitation costs more than any gap between the tools ever could.
So pick your poison. Whichever one is already in reach, already familiar, already one click away. Use it until you have an actual reason to switch, not a vague sense that somewhere out there is a better answer to a question you haven’t asked yet.
There is a scene in A Beautiful Mind that I did not understand at the time. Russell Crowe walks into the facility, looks up at the mezzanine, and sees a figure watching from the shadows. His question is immediate: “Who is Big Brother?”
I was fourteen. I did not know “Big Brother” was shorthand for the government. Moving on.
For years, whenever I heard the word governance, my mind went straight back to that moment, and that one question: “Who is Big Brother?”
Governance. Two syllables, but the root does all the heavy lifting: govern. To direct, to guide, to exercise authority over how a system operates.
Governance is the conversation nobody wants to have. It is also the one that reveals everything.
It exposes where an organization lacks discipline, or it proves how deliberate you are with your data, your environments, your applications, and the people who build them.
Governance is not about slowing innovation down. It is about establishing the guardrails that let you build useful things safely, repeatedly, and at a scale the business can sustain.
Governance in Dataverse
Too many organizations admit they have never had the Dataverse governance conversation. When asked why, the answer is almost always the same: we didn’t have the time. You make the time upfront, or you pay for it later.
Dataverse has governance built into its foundation. Configured correctly, it protects your data like a vault. When a CTO asks me directly if Dataverse is secure, I take it as a sign of leadership: they understand that convenience cannot outrun security.
With AI moving into every workflow, unmanaged data is an active liability. Without boundaries, models expose what should have stayed private. Do not wait for a Day Zero to start governing.
Governance is not one thing
Governance is not a switch you flip. It is not a single toggle, a compliance policy filed in a drawer, or “big brother” in IT approving access requests.
Governance is built on nouns: people, places, and things.
People: Who build, administer, support, and use the solution.
Places: Where the work lives: tenants, environments, and data boundaries.
Things: What is being governed: tables, flows, applications, credentials, and security roles.
If you cannot account for every person, place, and thing inside your architecture, you are not governing. You are guessing.
When you can account for the people, places, and things, governance stops being an abstraction. You can finally ask the questions that matter:
Who is accountable for the business outcome?
Where should the solution be built and operated?
What data is being managed?
Who can access the data?
Where is it allowed to go?
How do we safely change and support the solution over time?
Governance is a framework, not a finish line.
It is the operating model that defines who owns the outcome, where data can travel, and how systems evolve without breaking.
You do not become governed because you bought a platform. You become governed when your organization can answer those questions consistently, long before something goes wrong.
Risk Is the Starting Point
The governance model should scale with the consequence of getting it wrong. I’ve spent time on the other side of policy, building it rather than just living under it. When I started on the Power Platform, none of us knew what we had. My first few solutions were lucky: no sensitive data involved. Not every organization gets that luck and luck is not a governance model.
The solutions solved real problems, but the risk stayed low. If something broke, we could fix it. If it didn’t land, there wasn’t much on the line.
A change management app is not a department app. A department app is not a solution that manages client data, automates financial approvals, connects to an ERP, or becomes part of a process people rely on every day.
Governance should be proportional to risk. The more people, processes, money, customer data, or compliance obligations a solution touches, the more intentional its controls need to be. That intention has to rest on something: a foundation built before the risk arrives, not assembled after it does.
The Governance Foundation
Governance is a framework, and every framework needs a foundation: a north star to return to when things go wrong. That foundation rests on six pillars, and each one is a conversation you can have with your customer.
Pillar
Question it answers
What it looks like in Dataverse and Power Platform
Environment strategy
Where does this work belong?
Purpose-specific environments for development, testing, UAT, production, and lower-risk maker work
Business owner, product owner, technical owner, support path, documentation, monitoring, recovery plan
For years, on the other side of “big brother,” I never really considered these things. I was given a spec sheet and built where I was allowed to build. As I evolved into more of an architect role, these conversations became pivotal to how we designed solutions. This conversation is specific to Dataverse, but the six pillars aren’t. They apply, in some form, to every technology stack.
Environment Strategy
Environments are containers that house our solutions, and they have to be purposeful in how they’re built. Your environment design expresses what kinds of work the organization considers safe, experimental, supported, and production-ready.
Practical Baseline
Environment
Purpose
Who should work there
What belongs there
Personal/maker environment
Learning, prototypes, personal productivity
Individual makers
Low-risk experiments; no business-critical process or sensitive production data
Team or department environment
Shared but lower-risk solutions
Approved makers and team users
Department workflows, internal collaboration apps, limited-scope data
Best practice treats development, test, and production as separate worlds with separate occupants: makers and developers build, testers and administrators validate, and administrators and end users run what’s live. Each environment should be built with intent, not left to double as production by default.
Production is not a sandbox. It’s where the organization runs the process it has agreed to stand behind.
Security is about the business model
Environments decide where work happens. Security decides who can act once they’re there. A security model has to be functional, not just correct on paper. It should mirror the jobs people actually do, and the responsibility that comes with each one. I’ve seen security built too loose, exposing far more than it should. I’ve seen it built too tight, locking out the very users it was meant to serve. The details are where it lives or dies: does a requester get admin functions? How many rights does an admin actually need?
Project Intake Security Model
Example
Persona
Typical Dataverse access
Requestor
Create requests; read their own submissions and status
Read and approve commercial/financial components; access restricted financial fields
Executive sponsor
Read portfolio rollups and selected initiatives; approve stage gates
System administrator
Manage platform configuration; not automatically the business owner
External Notion audience
Receive only intentionally published, approved, minimized information, not direct unrestricted access
Security should mirror the business itself. Some roles operate on a need to know basis. Others, further up, carry broader access. The two should never intersect. The controller isn’t the CFO. The CFO isn’t the CEO. Separation of duties isn’t a technicality here, it’s the model.
Security should answer one question: what is this person responsible for? It should never be an accident of who happened to build the app.
Data Classification Drives the Controls
Before you decide what environment a solution belongs in, who should have access, or whether a connector is allowed, there’s a more basic question to answer: what kind of data are we actually working with?
Data classification is how you make that answer explicit. It’s the practice of identifying the sensitivity and business impact of the information a solution creates, stores, reads, changes, or sends somewhere else.
Classification isn’t about making every record feel important. It’s about understanding what happens if that data is exposed, changed incorrectly, lost, kept too long, or connected to the wrong system.
My first few Power Platform solutions were lucky. No sensitive data. No connections to critical systems. They never became business dependencies. But luck isn’t a governance strategy. The moment a solution touches client information, employee data, financial data, personally identifiable information, or anything regulated, the conversation changes. The classification should change the design.
A simple model
Four levels are enough for most organizations to start with.
Classification
Typical data
Governance implication
Public
Approved for anyone to see
Broad access is fine; validate publication and ownership of changes
Internal
Routine business information, not for public distribution
Authenticated internal access; normal ownership, retention, and sharing controls
Confidential
Client, employee, commercial, or business sensitive information
Regulated, financial, legal, credential, or highly sensitive personal data
Need to know access only; minimize use and copies; dedicated review and monitoring
A project name might be internal. A client’s delivery status might be confidential. A commercial estimate, a legal issue, an employee performance record: highly confidential. They can all live inside the same business process without sharing the same access model, integration path, or visibility.
Classification is not DLP
People blur these two constantly.
Data classification tells you how sensitive information is and how it should be handled. DLP, data loss prevention, is one of the controls that enforces part of that handling: specifically, how data moves between connectors and services.
Power Platform sorts connectors into business, non-business, and blocked groups, then controls which ones can be used together. That’s enforcement. Classification is the judgment that comes before it.
Concept
Question it answers
Data classification
How sensitive is this information?
Data ownership
Who decides how it should be used?
Dataverse security
Who can access or change it?
DLP policy
Which services can it move between?
Integration design
What data actually leaves, and why?
This matters even more with Notion
When we talk about surfacing Dataverse data somewhere else, like Notion, the question isn’t “can I connect these two systems.” The question is which fields are appropriate to publish, for what purpose, under whose approval, and what stays authoritative and protected in Dataverse.
A good integration doesn’t copy everything. It publishes the minimum useful information on purpose.
Questions worth asking
What data does this solution collect, create, update, display, or send elsewhere?
Which tables and fields hold personal, client, financial, employee, or regulated information?
Who owns the business definition and handling of that data?
What is the authoritative source for each important object?
Who should read, create, update, approve, export, share, or delete it?
Which systems are allowed to receive it?
What should stay out of reports, exports, copilots, and external workspaces?
How long do we keep it, and when does it get archived or deleted?
Data classification isn’t a sticker you put on information after it’s stored. It’s an architectural input. It should shape where the data lives, who can see it, how it moves, and whether it belongs in the solution at all.
DLP and Integrations
Once you know who’s responsible for what, the next question is where the data they touch is allowed to go. A connector is not a technical footnote. It is an exit door for your data.
Connecting Dataverse to another service is an architecture decision: where the data can go, what can move, who authorizes it, how that movement gets watched.
A conversation builders resist
This is the pillar that has annoyed me more than once, and the friction is by design. As a builder, I wanted to build the thing and move on. I knew how to use connectors. That didn’t mean it was the right use for the organization I was working with. Commercial cloud and government cloud don’t treat the same connector the same way. An industry can deny a connector outright. The conversation frustrates builders, sometimes architects too. It’s worth having anyway.
Questions to ask before you connect
Is the target system approved for this classification of data?
Is the integration one direction or bidirectional?
What is the authoritative system for each field?
Which fields are intentionally published, and which fields must remain in Dataverse?
Who owns the connection, credentials, and failure response?
What happens when a record is deleted, a schema changes, or an integration fails?
Does the DLP policy permit these connectors to be used together in the relevant environment?
The goal isn’t to stop data from leaving Dataverse. It’s to make sure every movement is intentional, appropriate, and accountable.
ALM turns a solution into Product
DLP protects data while it’s moving. ALM protects the solution itself as it moves through environments. If a solution matters, it has to be deployable and supportable without depending on memory or manual changes in production. The moment the business decides a solution matters, it stops being something someone built. It becomes a product.
A product gets everything it needs to succeed: automated deployments, lifecycle management, version control, and a release process the team can repeat without guesswork.
The baseline path
Build in a development environment.
Package tables, apps, flows, components, and configuration into a solution.
Test in a separate test or UAT environment.
Deploy approved changes to production.
Monitor behavior, document ownership, and manage future releases.
Microsoft treats solutions as the mechanism for moving Power Platform components between environments, and its own environment strategy guidance requires ALM for enterprise development: sandbox preproduction environments, managed solutions in production.
If the only deployment plan is “ask the person who built it to make the change in production,” the solution isn’t ready to be a business dependency. Pipelines, whether DevOps or Power Platform, exist so no one has to move a solution by hand. But once change stops depending on memory, someone still has to own what ships. That’s the last pillar: who’s accountable once the lights are on.
Ownership and Operating model
Governance isn’t governance without the people behind it, call it “big brother” if you like. Watching the solutions and environments matters, but watching alone isn’t enough. Most Power Platform risk is not caused by a table. It is caused by unclear accountability. Every part of the process needs a sponsor, an owner, a champion. Without one, the process fails. Identify these people early, and build a Center of Excellence around them.
For every production Dataverse solution, establish at least these roles:
Role
Accountable for
Business owner
Desired outcome, funding, process decisions, and prioritization
Data owner/steward
Definition, quality, retention, access expectations, and source-of-truth decisions
Product owner
Backlog, user needs, adoption, release priorities, and value realization
Technical owner
Architecture, integrations, ALM, technical health, and engineering standards
Incident routing, user support, documented response and escalation path
These roles don’t have to be six different people. A small team might combine several under one name. What matters is that each responsibility has a name attached to it, not a department.
When ownership is clear, incidents get resolved faster and decisions get made without escalation theater. When it isn’t, everyone assumes someone else is watching.
That’s the sixth pillar, and it closes the loop the other five opened. Environment strategy decides where something lives. Identity and access decide who can touch it. Data classification decides how sensitive it is. Integration and DLP decide where it’s allowed to go. Application lifecycle management decides how it changes. Ownership and operations decide who answers for all of it.
Governance Makes Scale Possible
Governance is not what you add after innovation. Governance is what lets innovation become reliable enough to scale.
It gives makers a safe place to experiment. It gives business teams confidence that the processes they depend on are supported. It gives IT a way to protect data without becoming the bottleneck for every idea.
Dataverse gives you the platform capabilities. Governance decides whether those capabilities become trusted business outcomes.
In Part 3, we get practical: what kind of work actually belongs in Dataverse? Because governance doesn’t start once data lands in the platform. It starts earlier, with the architecture decision of whether Dataverse is the right place for that work at all.